

Back in 2024 I wrote a post called Media Ownership. It was a rant on how you don’t really “own” any of the online digital media you consume through streaming services like Spotify, Netflix, and the like. Because these companies can (and often do) remove and modify the media they host, without your knowledge or consent, anytime they wish to do so.
While writing that post I realized that this doesn’t just apply to just streaming and entertainment, but to file hosting on the internet in general:
Of course, it’s easy enough to grasp that the shows you watch on Hulu or the songs you stream on Tidal aren’t yours. But what this also means is that you don’t own all of your half-finished Google Docs on your personal Google Drive, or your favourite vacation albums shared on Google Photos, or the billion Notes you’ve written to yourself that are now on iCloud. These files belong, first and foremost, to Google and Apple. If you lose your Gmail or iCloud account tomorrow, you lose access to these files, period.
The crux of that post was that:
You own something only if you can access it without the internet.
In the last couple of years there’s arisen another layer to the “ownership” aspect of digital media: that of AI legibility.
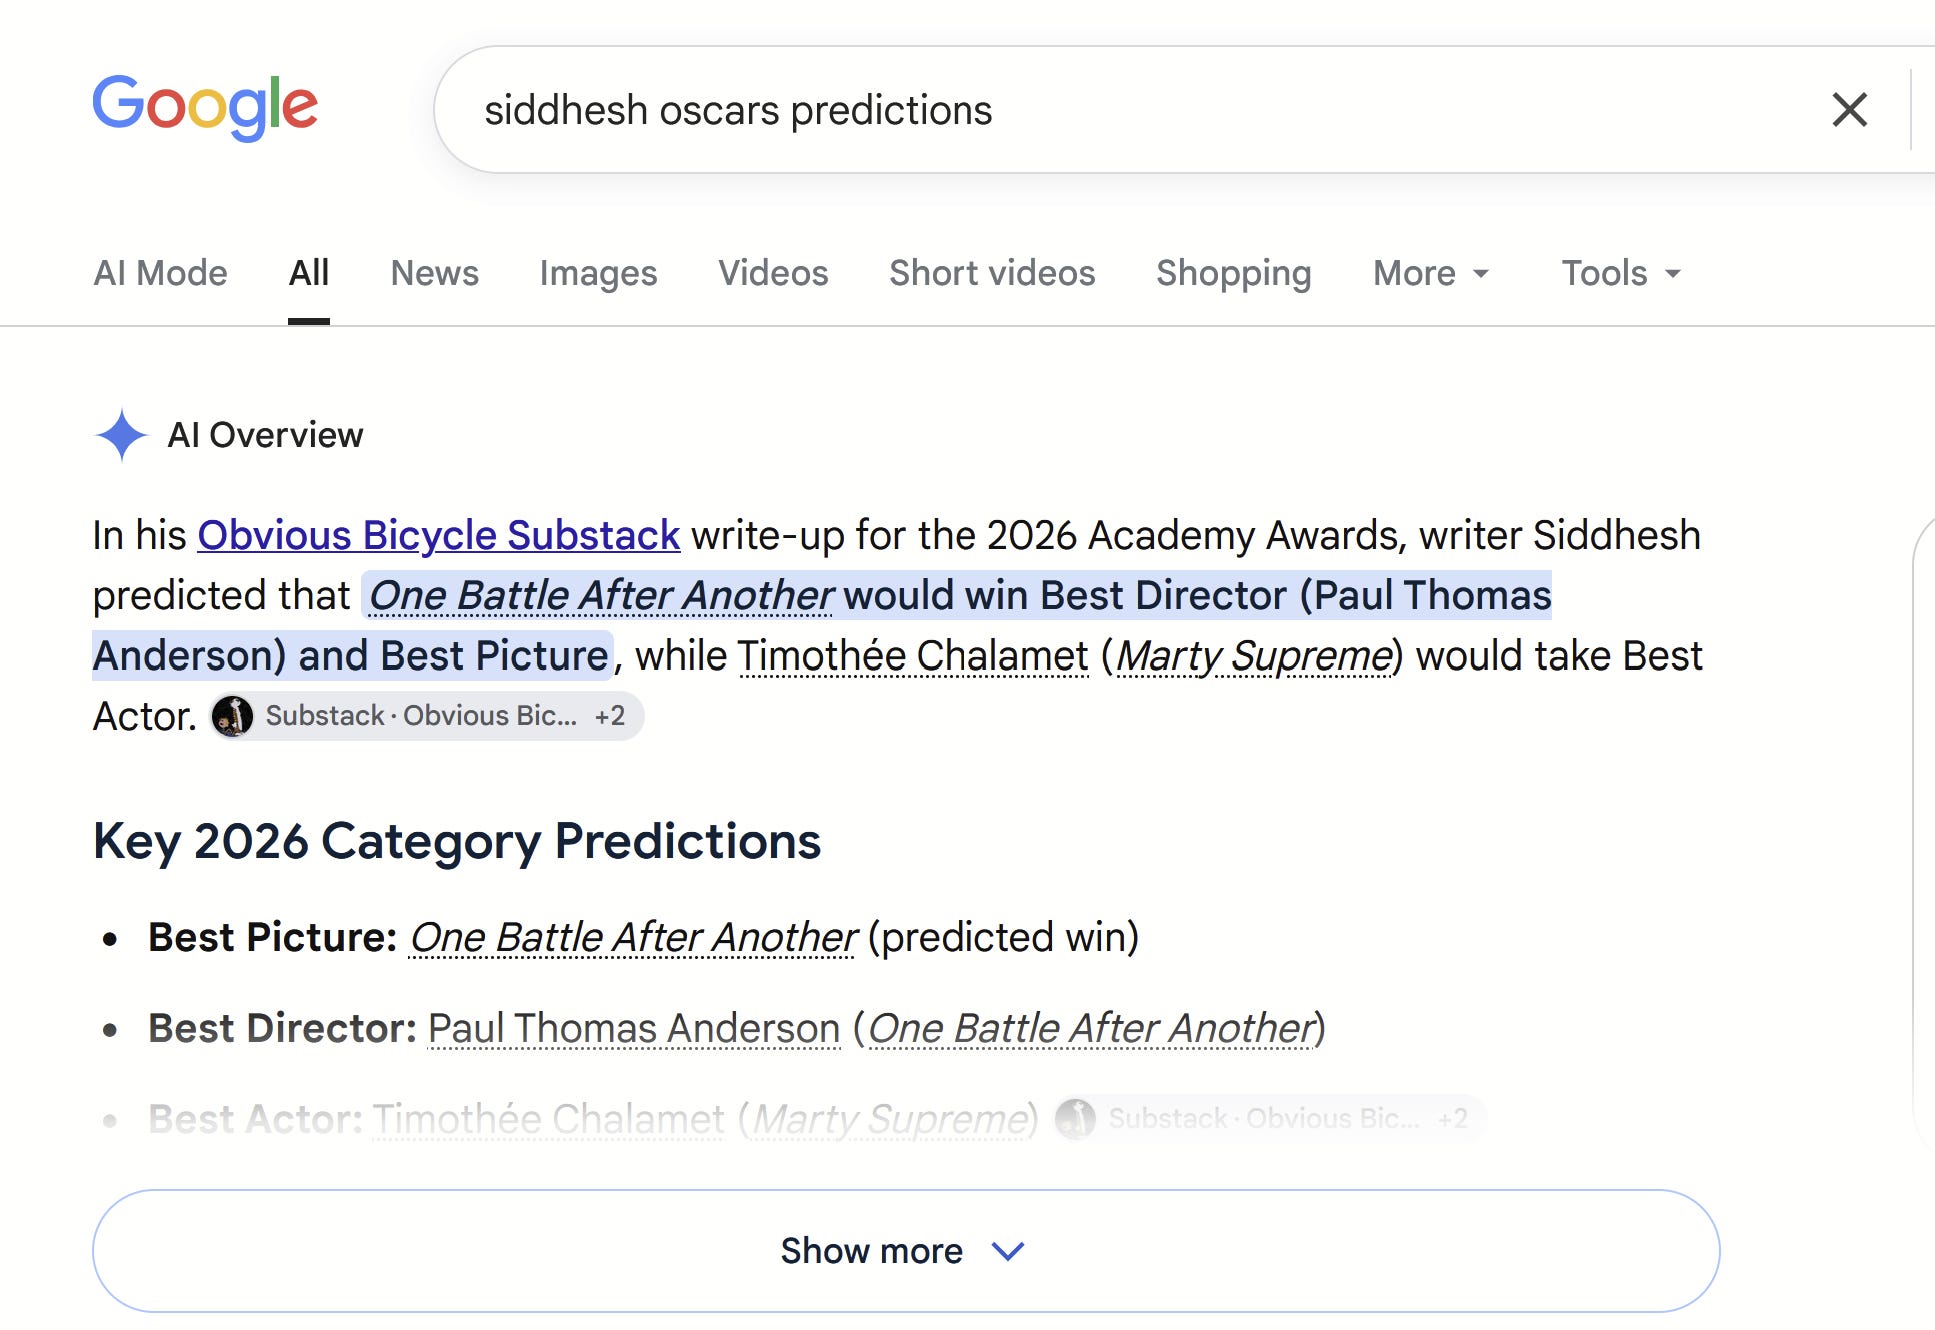
AI models have gotten exponentially better and far more agentic in the last couple of years. They’re multimodal, shockingly fast at scraping web content, and have been integrated into pretty much every Big Tech consumer product. I can even google one of my own blog posts and get an AI-generated summary of it in the search results:
Which I expect. But AI models that you do not control can now access your your personal data as well. Enterprise organizations like Google and Microsoft have integrated their AI tools into pretty much all of their products.
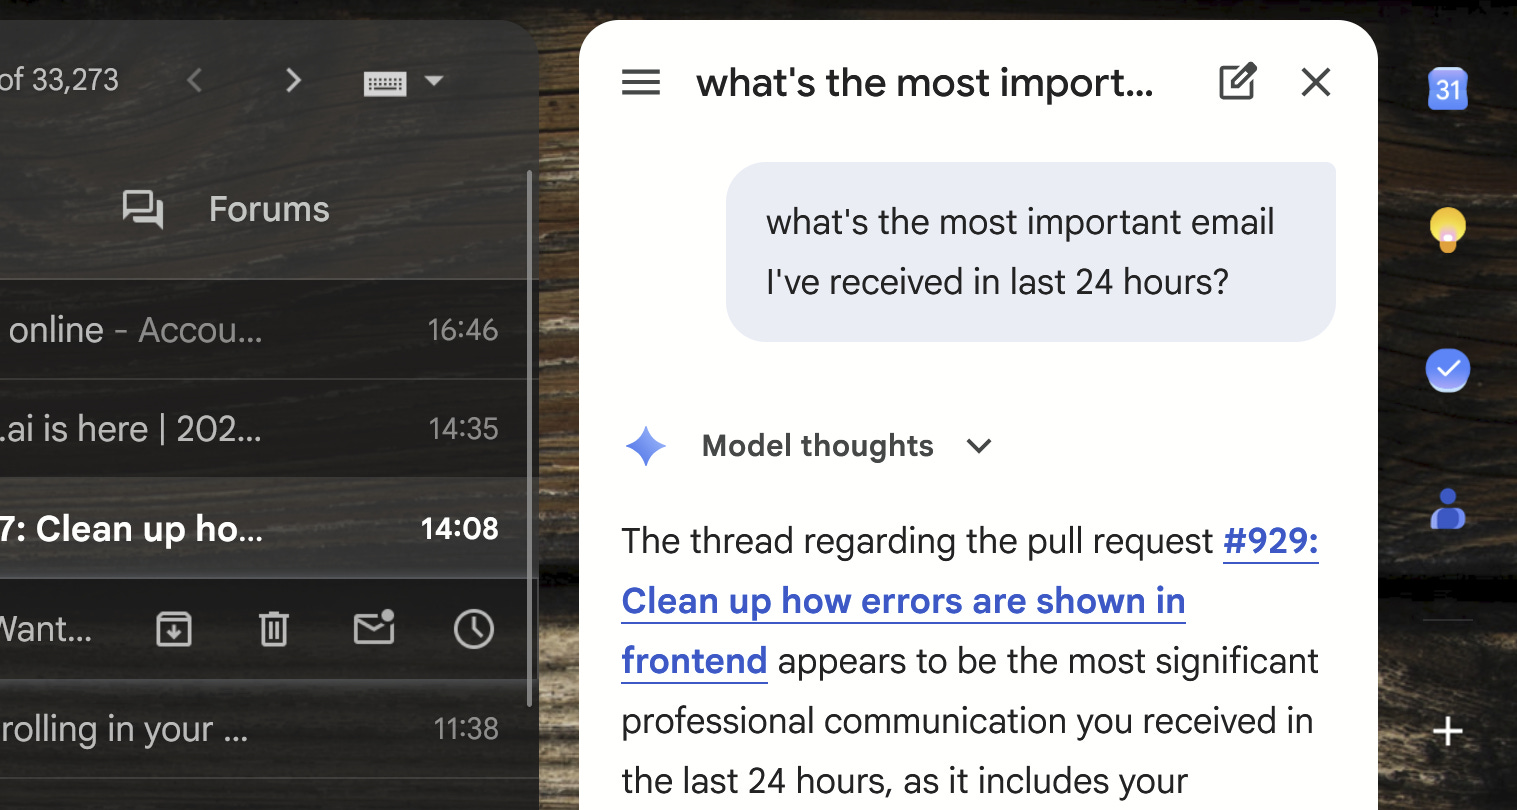
For example, Google’s AI model, Gemini, can read all my personal emails in my Gmail inbox, if it’s asked to answer any questions about them:
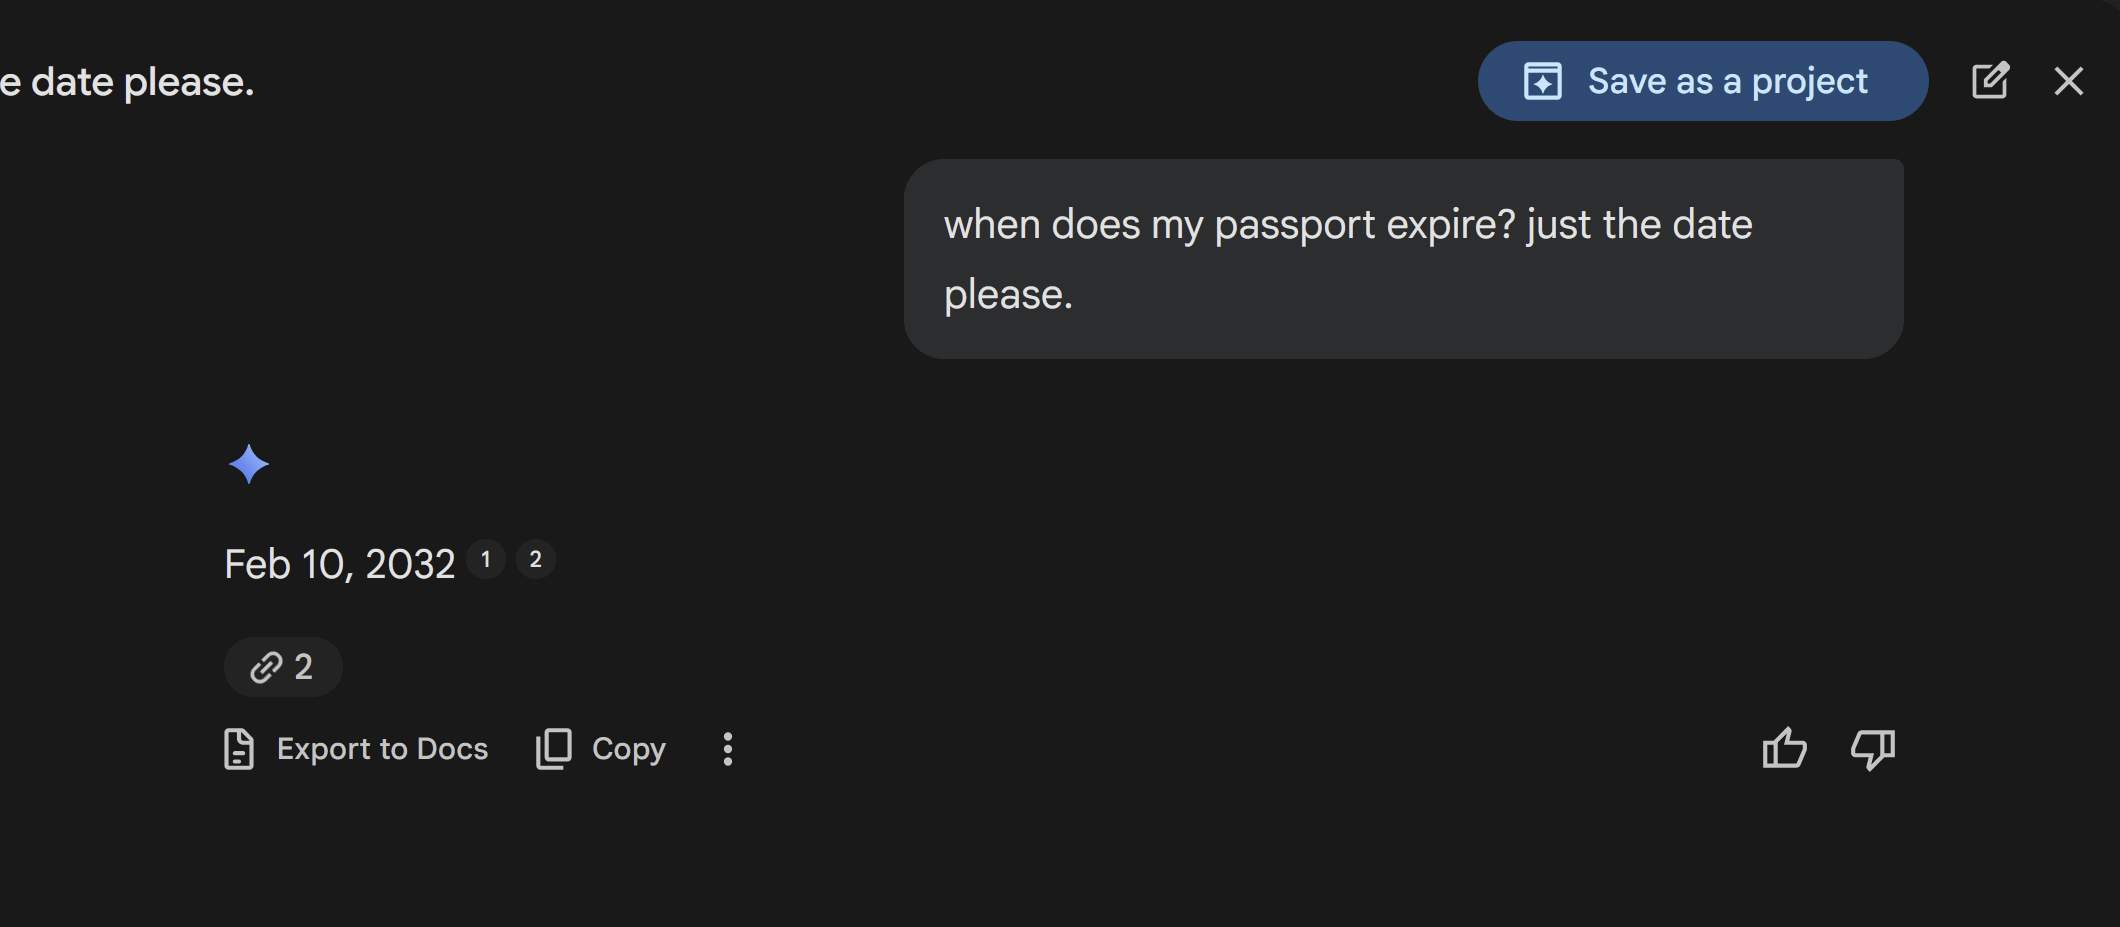
Gemini can also read all my personal documents in Google Drive, so as to help answer any questions about these files:
Now, I’m totally cool with Gemini returning an AI summary of my own blog post on a web search, because my blog is meant to be public. In a weird way I’m a bit flattered it bother scraping my pages at all.
But my emails and documents are (supposedly) private. No one else has access to my inbox, my Google Drive links aren’t shared, and both spaces contain personal information that I don’t want anyone parsing, machine or human. (It would be one thing if I manually fed my emails or documents into an AI tool for a specific task, but I didn’t.) At no point was I explicitly asked if I’d like to give Google permission to have their model get access to my personal information. And yet Gemini can now read everything on my account, if it so wishes.
Of course, I’m sure I “technically” consented to this some time or another; Google probably updated their Terms and Conditions to reflect this new change, which I probably clicked “accept” on while scrolling Twitter on some lazy Sunday morning.
But this isn’t about Google specifically—I’m just using them as an example throughout this post because my entire digital life exists on their suite. We can already see that tech companies have, in the last year or so, rushed to “embrace AI”, to get ahead of the curve, to add AI features to their products any way they can, the user experience be damned. (If you work in tech, you’ve probably experienced this firsthand.) Open any popular consumer software product and you will see a new button for an AI-related feature somewhere on the screen.
If we extrapolate this more broadly, we can confidently say that any company that hosts private user data of any kind is probably giving an AI model access to said data. Data has been the “new oil” for decades now, and with GenAI its value increases exponentially.
Imagine the sheer volume of text, image, and video content that is stored on the servers of products like YouTube, Facebook, Dropbox, Instagram, Slack, and WhatsApp, just to name a few. Data just lying around, unused, waiting to be fed to a model. . .
Now, I know I’m being a tad speculative with my whole, “AI has access to all your stuff!” mania. This might not be true for every product, every time. But it’s safe to assume that it is anyway, in the same vein that it’s safe to assume that any email you write could end up as a front-page newspaper headline the next day.
But then, you might ask, who cares if an AI model can read my data, as long as that data:
a) isn’t being used in training, and
b) does not leak out of my account?
One would assume that a company like Google has taken precautions to ensure that my personal information is not used to train their models and used only as inference, meaning that none of my information will be used to update their model weights, meaning that my data won’t leak through another user talking to Gemini. Meaning that you can’t ask Gemini, “What’s Siddhesh’s passport number?” and get an answer, because Gemini simply does not know, because my passport PDF was never fed into its training dataset.
But here’s the thing: this might be true, but it’s true for now. At the end of the day it’s just an assumption. Because the AI plumbing is already in place, because the infrastructure already exists for their model to read my entire inbox and storage on demand, if Google decided tomorrow that they do want to somehow use my information in their training dataset, it would take relatively very little effort for them to do so, and I would be none the wiser.
I say this because it’s already happened. If you were a regular user of Claude, you would assume your chats weren’t being used to train Anthropic’s next release, but in 2025, Anthropic flipped this exact switch:
“Previously, the company did not train its generative AI models on user chats. When Anthropic’s privacy policy updates on October 8 to start allowing for this, users will have to opt out, or else their new chat logs and coding tasks will be used to train future Anthropic models.”
I’m sure these companies probably have some mechanism to ensure that sensitive and private details don’t end up in the training corpus. (Again, an assumption more than anything.) But I’m less concerned about my social security number getting leaked than I am made uncomfortable by the fact that the next version of Claude or ChatGPT is being trained on words I’m typing to it in a private chat.
Even keeping the training issue aside, knowing an AI model can look through everything you upload on a file system is still weirdly invasive. Maybe it’s not not invasive in the same sense of having a human being look through your stuff would be, but LLM’s are intelligent enough for that feeling to definitely be non-zero. If I’m writing something personal in a Google Doc, I want to know for a fact that nobody, human or machine, can access or read it. Whether the machine does anything invasive with that information is irrelevant.
All of this is made worse whenever companies sneakily pilot AI features onto their platforms without explicitly asking you if you’re okay with it. Just last month, Instagram added a new feature that would let anyone create AI-generated images from other people’s photos, with every user on the platform opted-in to this by default (?!). The pushback over privacy concerns was so intense that they were forced to discontinue the feature entirely. But the damage was done. A friend of mine got so spooked they subsequently deleted all their pictures on Instagram:


This invasiveness can go even farther. What’s stopping someone from setting up workflows that can get triggered by these models if certain criteria are met? ChatGPT could be set up to directly contact the suicide hotline if you say something worrying to it. Gemini could be set up to contact the local authorities if you’re writing something “inappropriate” in a Google Doc. The possibilities are endless.
If these hypotheticals sound implausible, or even Orwellian, know that similar things have already happened. Just this month, the FBI arrested a teacher in Illinois literally an hour after she sent a private text on Snapchat joking about shooting a student, clearly in frustration. (Of course they found no credible threat and eventually let her go.) How did this happen so quickly? Snapchat has an AI content moderation system set up to scan private messages that didn’t understand the humorous intent behind her text, but then proceeded to not just internally flag the text, but autonomously reported it to the police (!?). A ridiculous overreach and a gross invasion of privacy, if there ever was one.
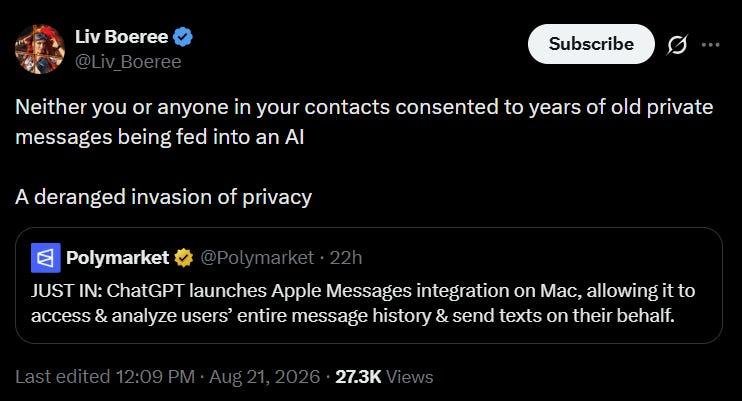
And speaking of texts, literally in the very week I was writing this post, OpenAI announced a new messaging plugin, which lets you add ChatGPT into iMessage and lets GPT read, search through, and draft text messages on your behalf. Which means that ChatGPT has full access to a supposedly private and encrypted conversation history between two people, that might go back many years and thousands of messages into the past, even if one of the two people integrates it into their messaging app.
To this you might say: of course, I would never have to worry about any of this, because I’m a good person. I would never say or write something inappropriate worth getting flagged, nor would I ever write something that might be problematic if leaked. But as anyone who’s been online in the last decade knows, the goalposts for what’s “inappropriate” change with the times, moral standards are very malleable, and you never know who’s going to be next on the chopping block.
“If you give me six lines written by the hand of the most honest of men, I will find something in them which will hang him.”
- Cardinal Richelieu
All of which brings us back to the concept of ownership, which for digital media is getting increasingly trickier to define. In the 2024 post I defined it on the basis of access: you own something if you can get to it without the internet. But we must now define it on the basis of exclusivity as well: you own something only if you can keep others out—human and machine. Because no AI or human can access any words I might write in a physical notebook, or read from the printed documents stacked inside the folder sitting on my desk, without first breaking into my house. That’s real privacy. That’s how I know I truly own those documents and that writing.
All of which leads us to another principle about digital media:
You own something only if no other entity can access it without your consent.
This makes me an even bigger fan of tools like Obsidian, tools that prioritize your privacy and local file ownership above everything else, tools that I know for a fact do not scan or parse or access your files in any sense.
Because literally everything we do is digital now. All our most important information is stored digitally, we communicate digitally, we manage our entire lives on the cloud. Even our physical actions are factories for generating digital data—every purchase you make is another line in your credit card statement, every intersection you drive through is another image taken by a Flock Camera. We are generators of data, data which is ripe to be fed into GenAI models to train on and potentially do so much with: recognize our behavior patterns, sell us stuff, monitor our behavior, and decide if we get to partake in The System or not. I can’t help but shake the feeling that there’s no real sense of privacy left now, no concept of true media ownership in the digital realm, that even when I simply exist as a human outside my home I’m somehow manufacturing data for a tech company to intake as fodder just by virtue of existing, that I’m being monitored and scanned and analyzed and “watched” by a machine in some sense with every single action I take.
But who watches the watchmen?